
For twenty years, "crawler" mostly meant Googlebot and Bingbot. Now your server logs are full of GPTBot, ClaudeBot, PerplexityBot, and a dozen other user agents, and each one wants something different from your pages.
The biggest misunderstanding is treating "AI crawlers" as one thing. Most AI companies run several bots with different jobs, and a robots.txt rule for one does not touch the others. This guide explains how AI crawlers differ from traditional search engine crawlers, how to control each one in robots.txt, how to verify who is really crawling, and what your server logs reveal.
Last reviewed: [add date]. Bot names, user agent tokens, and crawler policies change often, so check each operator's documentation before changing your robots.txt.
How traditional search crawlers work
Googlebot and Bingbot do one main job: fetch pages so they can be indexed, ranked, and shown in search results.
Blocking them takes you out of their search results. That is why a stray Disallow: / for Googlebot is one of the most damaging mistakes in technical SEO.
AI crawlers come in three types
The group a bot belongs to decides what blocking it actually does.
| Operator | Training | Search index | User-triggered |
|---|---|---|---|
| OpenAI | GPTBot | OAI-SearchBot | ChatGPT-User |
| Anthropic | ClaudeBot | Claude-SearchBot | Claude-User |
| Perplexity | (none listed) | PerplexityBot | Perplexity-User |
User-triggered fetchers are where policies differ most. Anthropic states that all its bots, including Claude-User, honor robots.txt. OpenAI and Perplexity have said user-initiated fetches may not follow robots.txt the same way automated crawling does. If keeping content out of AI tools completely matters, robots.txt alone may not be enough.
Block a bot, not a company.
Tokens that are not crawlers
What actually differs between AI and search crawlers
| Search crawlers | AI crawlers | |
|---|---|---|
| Main purpose | Build a search index | Model training, an AI search index, or live fetches for a user |
| Bots per operator | Mostly one main bot | Often three, each controlled separately |
| JavaScript | Googlebot and Bingbot render it | Many appear to read only raw HTML |
| Effect of blocking | Removed from search results | Depends entirely on which bot you block |
| Verification | Reverse DNS and published IP ranges | Published IP ranges from some operators, inconsistent across others |
| Crawl-delay | Ignored by Googlebot, respected by Bing | Supported by some (Anthropic documents it), not all |
The JavaScript row matters most. If main content only appears after client-side rendering, a crawler that reads raw HTML sees an empty shell. Content you want AI search tools to find and cite belongs in the HTML your server sends, through server-side rendering or static generation. Our JavaScript SEO guide covers raw vs. rendered HTML.
How to write robots.txt for AI crawlers
Each bot follows the most specific user-agent group that names it. A common setup allows AI search and live fetches but opts out of training:
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: Google-Extended
Disallow: /

User-agent: OAI-SearchBot
Allow: /

User-agent: Claude-SearchBot
Allow: /

User-agent: PerplexityBot
Allow: /

User-agent: *
Allow: /

Sitemap: https://example.com/sitemap.xml01A named group replaces the * group
Once you add User-agent: GPTBot, rules under User-agent: * such as Disallow: /admin/ no longer apply to GPTBot. Repeat them in each named group.
02robots.txt is a request, not a lock
Well-behaved bots follow it. Scrapers pretending to be GPTBot will not. Use authentication or server-level blocking for private content.
03Blocking by IP can backfire
Anthropic notes that blocking its IPs may stop its bots from reading your robots.txt at all, so an IP-based opt-out may not work reliably.
04Old tokens linger
Many files still list deprecated names like anthropic-ai or Claude-Web. Harmless, but they do not control current bots. Test your rules with the free robots.txt checker.
How to verify who is really crawling
User-agent strings are trivial to spoof. Anyone can send User-Agent: Googlebot. Verify the important ones before acting on your logs:
| Bot | How to verify | Reliability |
|---|---|---|
| Googlebot | Reverse DNS resolves to googlebot.com or google.com, then forward lookup returns the same IP. Google also publishes crawler IP ranges as JSON. | Strong |
| Bingbot | Reverse DNS resolves to search.msn.com. Bing Webmaster Tools also has a verification tool. | Strong |
| AI crawlers | Some operators, including OpenAI, publish IP ranges. A "GPTBot" request from an IP not on OpenAI's list is not GPTBot. | Varies |
What your server logs can tell you
A site crawl shows what bots could access. Server logs show what they actually requested. You need both.
- Which bots visit at all. Many sites find AI bots visit far more often than expected, or not at all.
- Status codes per bot. Mostly 403s or 429s means something is blocking it, often a firewall, WAF, or CDN bot protection rule.
- What they request. Important pages, or mostly old URLs, parameters, and 404s?
- Whether they obey robots.txt. Requests from a verified bot to a disallowed path are worth reporting to the operator.
- Load. A
Crawl-delay(for bots that support it) or temporary429and503responses can slow a heavy bot. Google advises against returning those to Googlebot for long periods.
Logs usually live with your host, CDN, or server, not in a crawler, so this part needs access to those systems.
A crawl shows what bots could see. Logs show what they did.
A quick AI crawler audit checklist
Checking AI crawler access with SiteAuditLint
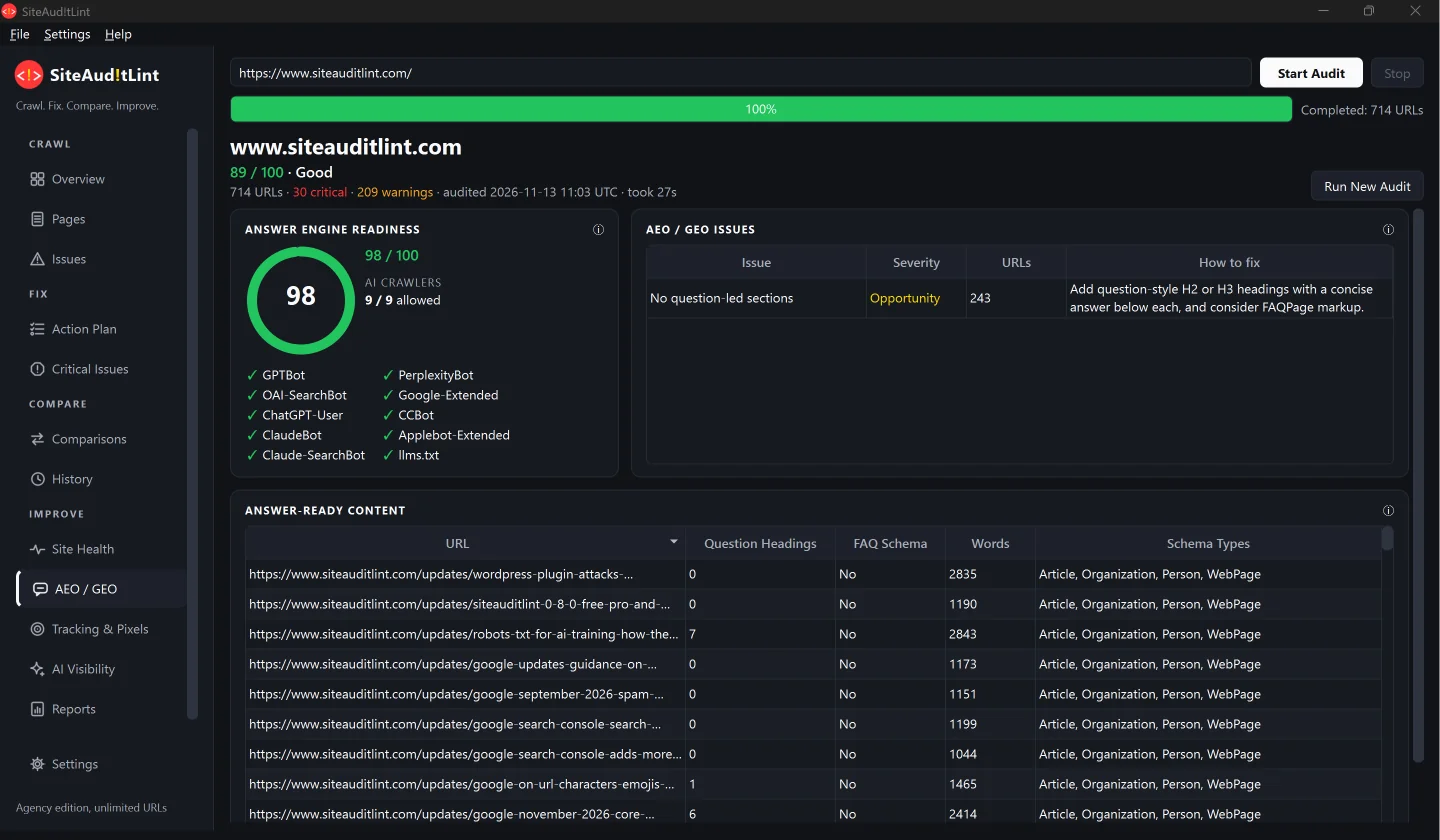
The SiteAuditLint AEO / GEO audit checks nine major AI crawlers, including GPTBot, ClaudeBot, and PerplexityBot, against your robots.txt and shows which are allowed or blocked. It also detects llms.txt, a proposed file for guiding AI tools that major search engines have not confirmed as a ranking signal, and flags content structure issues. It all rolls up into an Answer Engine Readiness score.
Access is only half the question. The AI visibility tracker runs your own prompts through ChatGPT, Gemini, Claude, and Perplexity and reports how often your pages are cited, so you can see whether allowing those crawlers is paying off.
On our own site (714 URLs, audited November 13, 2026), all nine AI crawler checks passed and Answer Engine Readiness scored 98 out of 100. The audit still flagged 243 pages with no question-led sections, a reminder that access alone does not make content easy for answer engines to extract and cite.
Frequently asked questions
What is the difference between AI crawlers and search engine crawlers?
Search engine crawlers like Googlebot and Bingbot fetch pages to build a search index. AI crawlers may collect content for model training, build an AI search index, or fetch a page live because a user asked, and one AI company often runs a separate bot for each job.
Does blocking GPTBot remove my site from ChatGPT search?
No. GPTBot is OpenAI's training crawler. ChatGPT search relies on OAI-SearchBot, and live fetches come from ChatGPT-User, so each needs its own robots.txt rule.
Does blocking Google-Extended remove me from AI Overviews?
No. Google-Extended controls whether your content is used for Gemini training and grounding. AI Overviews are part of Google Search, which is governed by Googlebot.
Do AI crawlers render JavaScript?
Many appear to read only raw HTML. If your main content appears only after client-side rendering, AI search tools may see an empty page, so serve important content in the initial HTML.
How do I know if a bot claiming to be GPTBot is real?
Check the request IP against the IP ranges OpenAI publishes. User-agent strings are easy to fake, so a request from an IP outside the published list is not GPTBot.
Is robots.txt enough to keep content out of AI tools?
Not always. Well-behaved bots follow it, but some user-triggered fetchers may not apply it the same way, and scrapers ignore it. Use authentication or server-level blocking for content that must stay private.
Related reading
Decide. Write. Verify. Serve.
Decide per bot, write each rule explicitly, verify who is really visiting, and keep the content you want found in the raw HTML.
AI search does not replace traditional search. It adds a second set of crawlers with different rules, and your robots.txt now has to speak to both.
One company, three bots